H3-Image Day-0 Support: 4K in 0.87s with Vera Rubin
·9 min read
H3-Image on Vera Rubin: 0.87-second 4K generation or 6,115 images/hour on four GPUs, with projected API revenue and support across consumer and data-center hardware.
6 posts
H3-Image on Vera Rubin: 0.87-second 4K generation or 6,115 images/hour on four GPUs, with projected API revenue and support across consumer and data-center hardware.
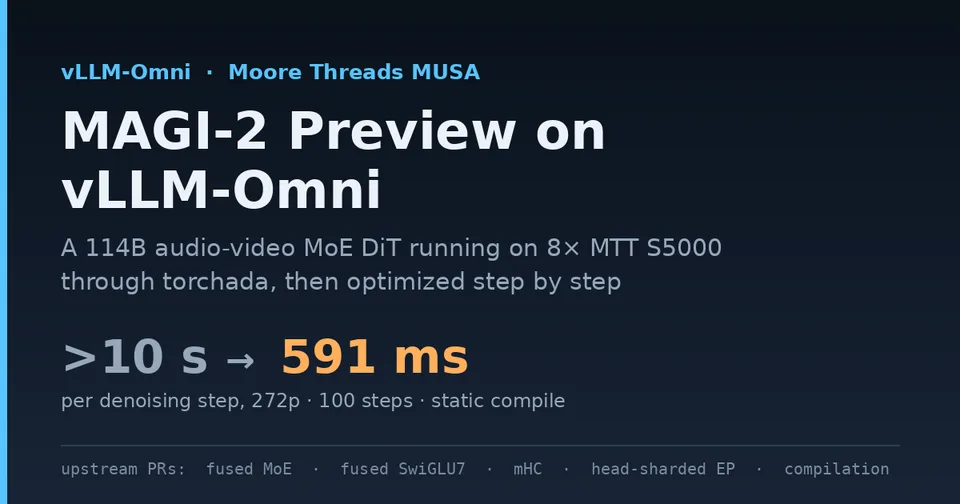
vLLM-Omni runs Sand AI's MAGI-2 Preview audio-video generation model on eight Moore Threads MTT S5000 GPUs through torchada's CUDA compatibility layer, then optimizes MoE, mHC, attention, parallelism, and compilation.
How vLLM-Omni optimizes and scales the complete MiniMax H3 stack, then integrates FastVideo’s four-step FastH3 for generation faster than playback.
Distributed Layerwise Offload shards and streams DiT weights across devices, serving a measured 124 GB Cosmos3 model on 64 GB HBM and estimating a path toward 200B+ models.
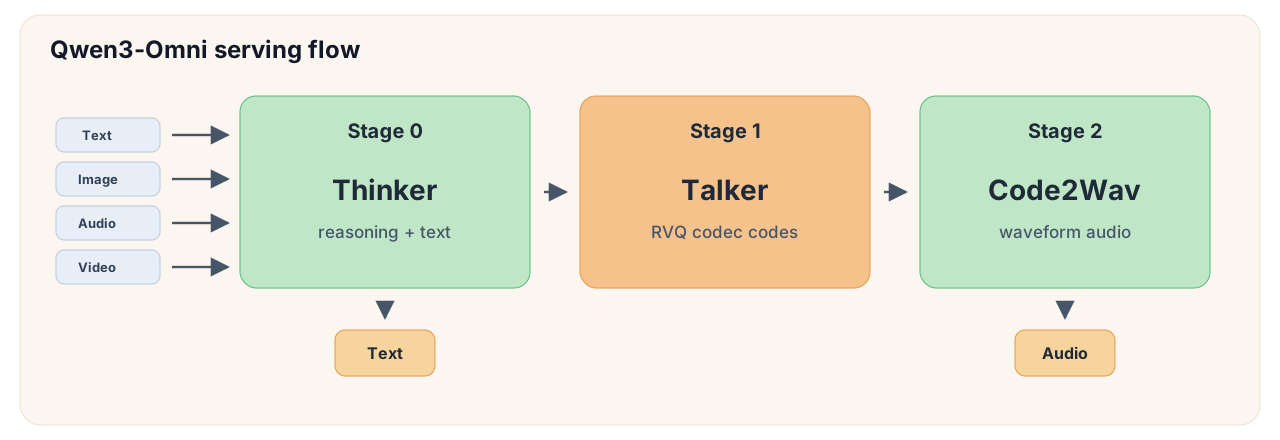
How vLLM-Omni serves and optimizes Qwen3-Omni with staged Thinker-Talker-Code2Wav execution, batching, CUDA Graphs, async chunk, async output, replicas, hot-path cleanup, and perf validation.
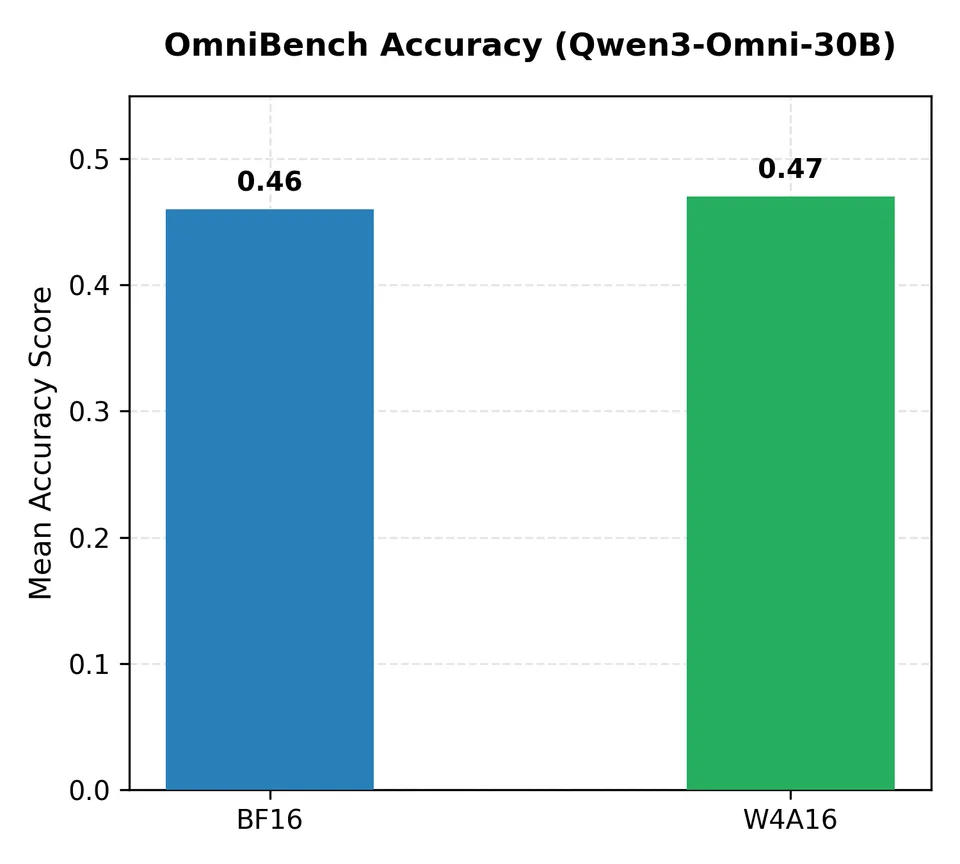
How AutoRound integrates with vLLM-Omni to serve W4A16 quantized multimodal, diffusion, image, and video models with smaller checkpoints, preserved quality, Intel XPU acceleration, and NVIDIA GPU support.